Chenyu Zhou

Hi  , This is Chenyu (周宸宇 in Chinese)!
I am currently a third-year PhD student in Institute of Intelligent Computing, Antai College of Economics and Management at Shanghai Jiao Tong University. I’m supervised by Prof. Yinyu Ye and Prof. Dongdong Ge.
My research interests center on the application of large language models and optimization in Operations Research and FinTech.
I am a gold medalist in the Asian regional contest of the International Collegiate Programming Contest (ACM-ICPC). I have served as an AI researcher at Cardinal Operations(杉数科技), Tencent(腾讯), OPPO, and Meituan(美团).
Prior to my PhD, I worked in quantitative investment at Ubiquant Investment(九坤投资), Harvest Fund(嘉实基金), and JZL Capital(君理资本). I also led our team to 7th place in China in the Global Management Challenge in 2021.
news
| Sep 28, 2026 | We released a new paper Learning to Optimize through Solver-Grounded Self-Play  ! |
|---|---|
| Aug 20, 2026 | One paper has been accepted to Findings of EMNLP 2026  ! |
| Jul 17, 2026 | I will present OR-Space: A Full-Lifecycle Workspace Benchmark for Industrial Optimization Agents at the 2026 POMS China International Conference in Xi’an. |
| Jul 14, 2026 | I will give an invited talk titled Towards Fine-Grained Supervision for Operations Research Language Models at IFORS 2026 in the invited session “Leverage LLM for Operations Research: Formulation and Solution.” |
| Jul 11, 2026 | Our paper SIGMA: Semantic-Informed Grounded Multimodal Alignment for Image Restoration has been accepted by the 34th ACM International Conference on Multimedia (ACM MM 2026) ! |
selected publications
* Equal contribution.
- Preprint
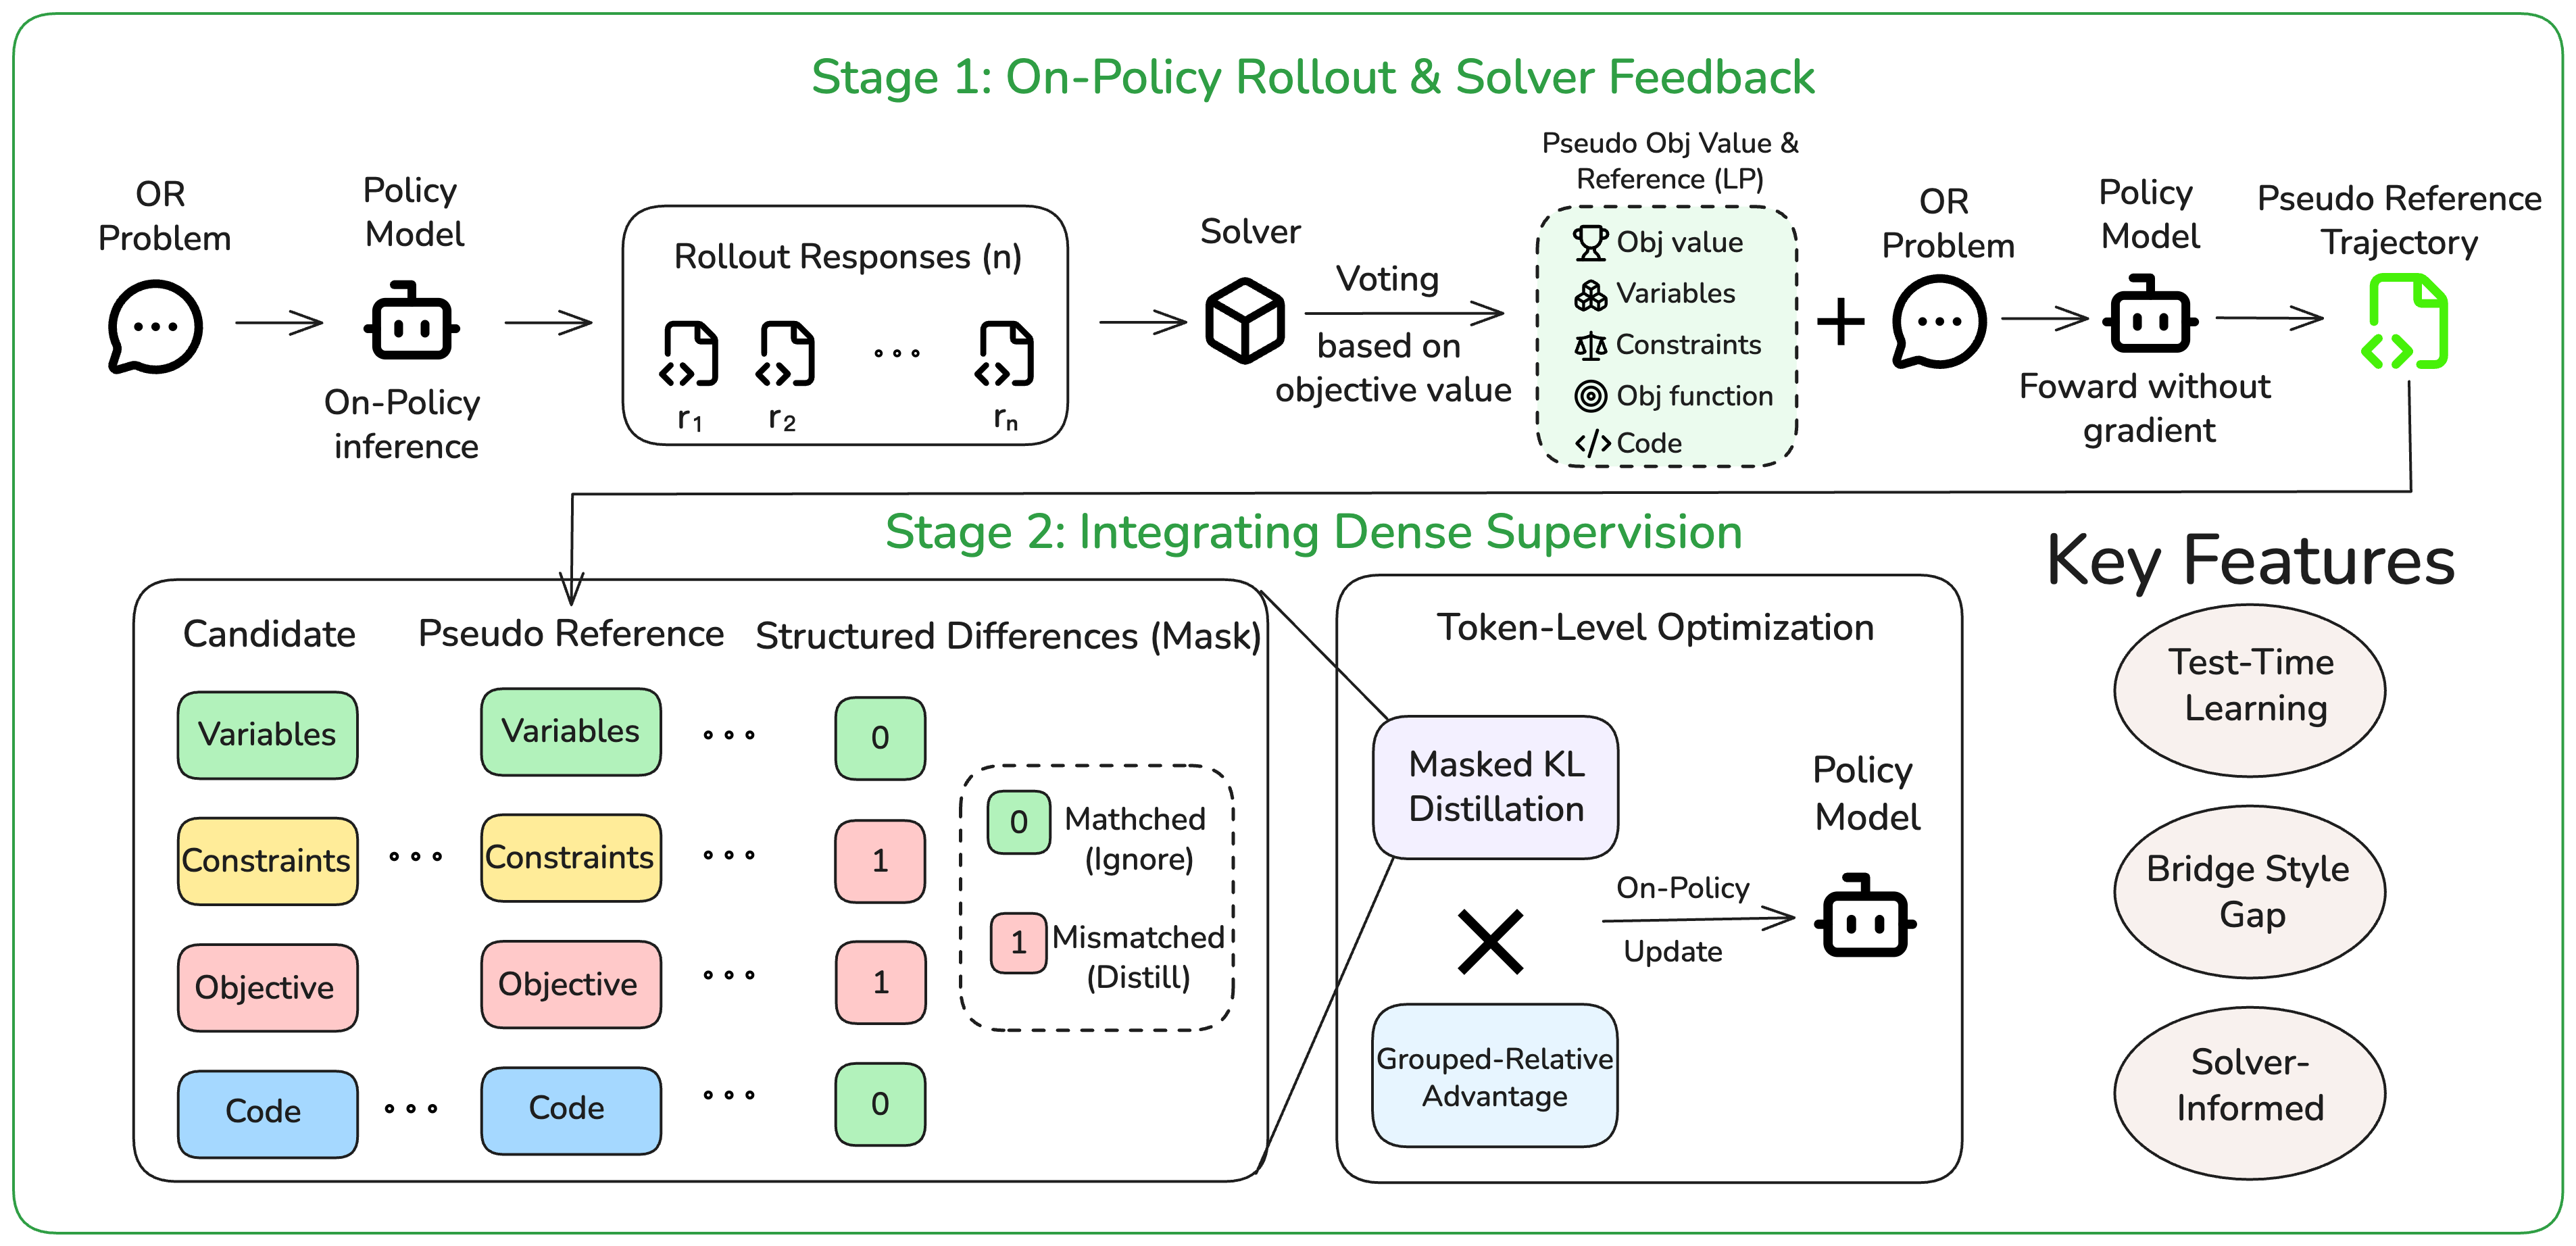 Beyond Verified Answers: Solver-Informed Self-Distillation for Bootstrapping Operations Research Language ModelsRui Zhu*, Minglong Cao*, Chenyu Zhou*, Jianghao Lin, and Dongdong GearXiv preprint arXiv:2609.09957, 2026
Modern large language models (LLMs) can translate natural-language descriptions into operations research (OR) formulations. Post-training techniques including reinforcement learning and on-policy self-distillation have further improved this capability. However, three limitations remain in training LLMs for OR formulations. First, training commonly relies on synthetic formulations validated by human experts or stronger models, constraining scalable supervision. Second, credit assignment is either coarse or costly: outcome rewards score an entire trajectory without locating the responsible modeling decision, whereas process-level supervision requires an additional evaluator. Third, privileged self-distillation can induce style mismatch by using solver context unavailable at deployment. We find that a model can improve from solver-artifact feedback generated by its own rollouts, making self-distillation a practical, evaluator-free source of dense supervision. Therefore, we propose SOLID: Solver-Informed On-Policy LearnIng through Self-Distillation, a novel framework for self-improving OR language models without verified answers or external evaluators. SOLID executes candidate programs from multiple rollouts, clusters their objectives, and selects a majority-group artifact as a pseudo-reference. The model then performs updates using group-relative advantages and dense self-supervision signals. Across multiple OR benchmarks, SOLID improves solution accuracy for both general-purpose and OR-tuned models over outcome-only group-relative training. These results show that solver artifacts can support scalable self-improvement without trusted answers.
BibTeX@article{ZhuSOLID2026, title = {Beyond Verified Answers: Solver-Informed Self-Distillation for Bootstrapping Operations Research Language Models}, author = {Zhu, Rui and Cao, Minglong and Zhou, Chenyu and Lin, Jianghao and Ge, Dongdong}, journal = {arXiv preprint arXiv:2609.09957}, year = {2026}, } - Preprint
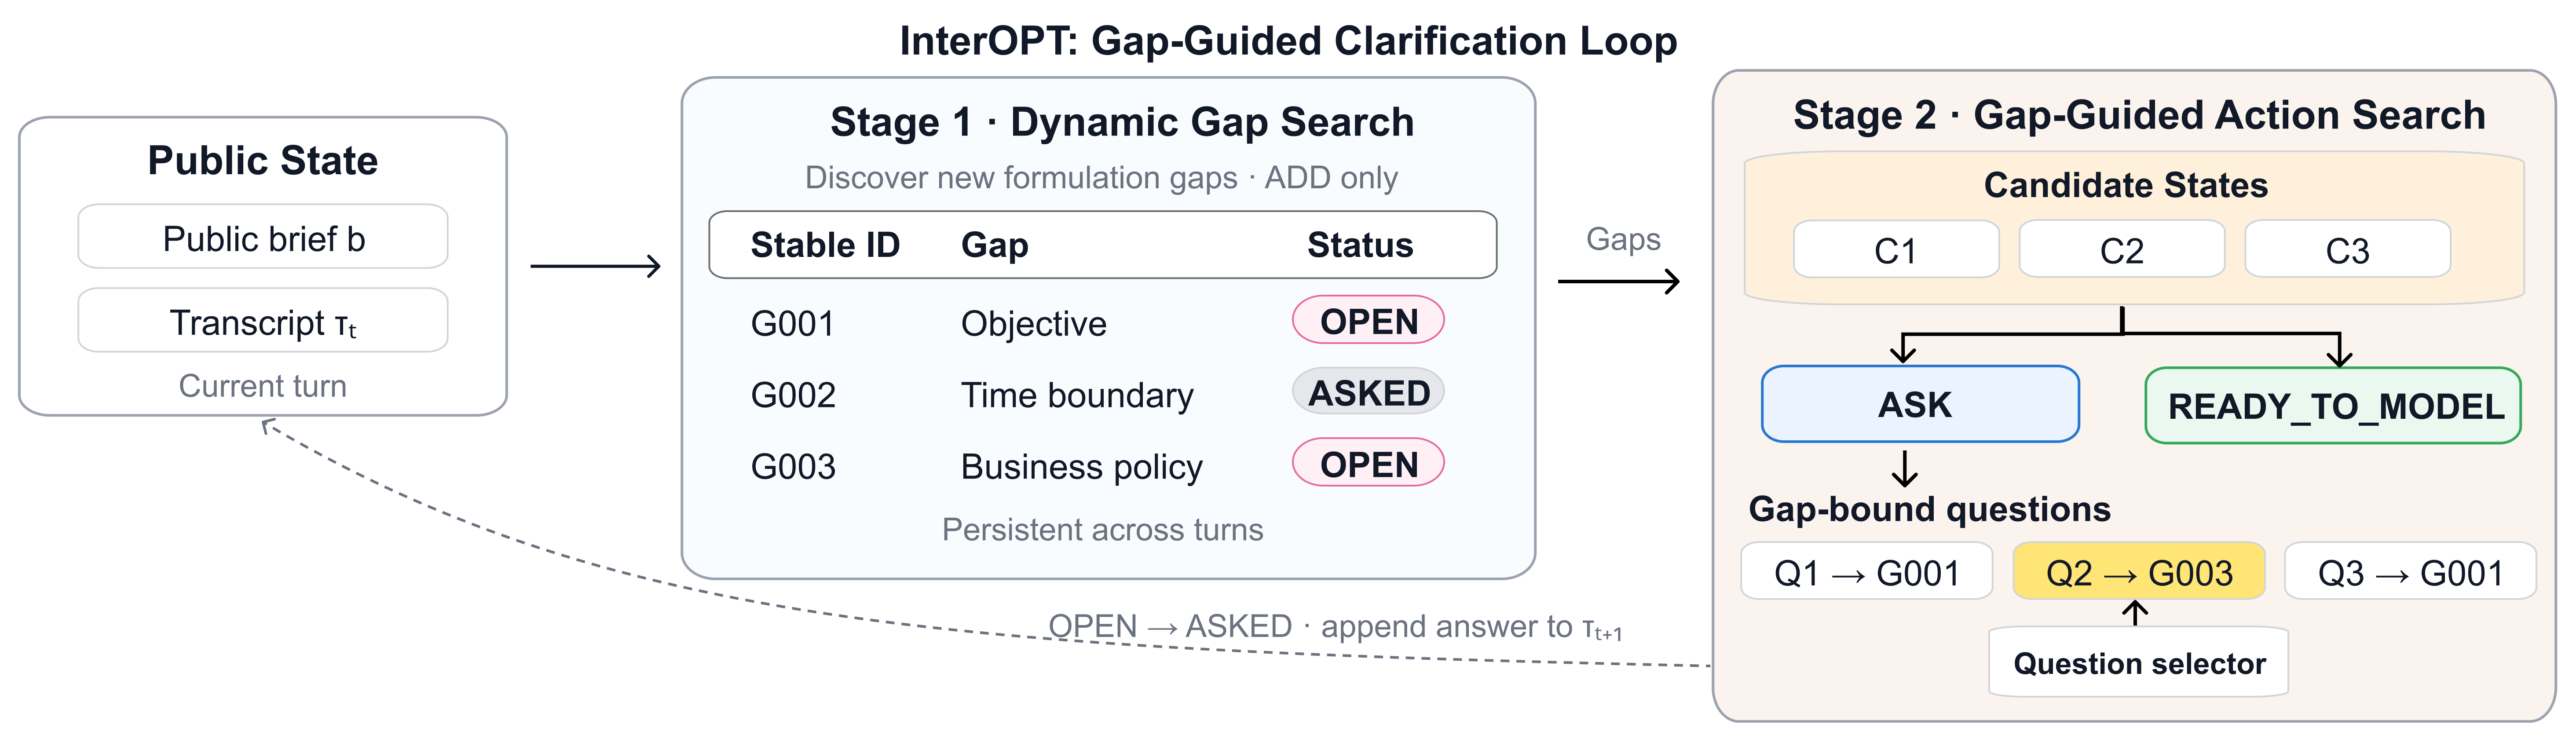 Ask Before You Optimize: Dynamic Pre-Formulation Clarification for Interactive OptimizationSihan Ge*, Yichen Lin*, Chenyu Zhou*, Jianghao Lin, Tao Yao, and Dongdong GearXiv preprint arXiv:2609.05258, 2026
Large language models (LLMs) are increasingly used to formulate optimization models from natural-language problem descriptions, yet realistic operations research (OR) requests are often incomplete: missing objectives, constraints, or business rules can change the resulting mathematical program. Existing evaluations largely assume a complete specification and therefore overlook whether an agent knows when clarification is needed before modeling. We introduce OR-Clarify, a benchmark for pre-formulation clarification. Each task presents a partial public problem description, withholds structured hidden slots, and evaluates agents through bounded interaction with a simulated user. The benchmark supports both open-ended and choice-based clarification, and measures slot recovery, stopping behavior, silent assumptions, and interaction cost. We further propose Interactive Optimization (InterOPT), a two-stage framework that identifies unresolved formulation-critical gaps and uses them to guide whether to ask the next question or to stop. In our choice-based experiments, InterOPT substantially outperforms all baselines in exact slot recovery; in the open-ended setting, it remains competitive with strong prior methods. Together, OR-Clarify and InterOPT reframe OR assistance as a selective completeness decision: clarify when needed, stop when ready, and quantify what remains missing.
BibTeX@article{GeInterOPT2026, title = {Ask Before You Optimize: Dynamic Pre-Formulation Clarification for Interactive Optimization}, author = {Ge, Sihan and Lin, Yichen and Zhou, Chenyu and Lin, Jianghao and Yao, Tao and Ge, Dongdong}, journal = {arXiv preprint arXiv:2609.05258}, year = {2026}, } - ACM MM 2026
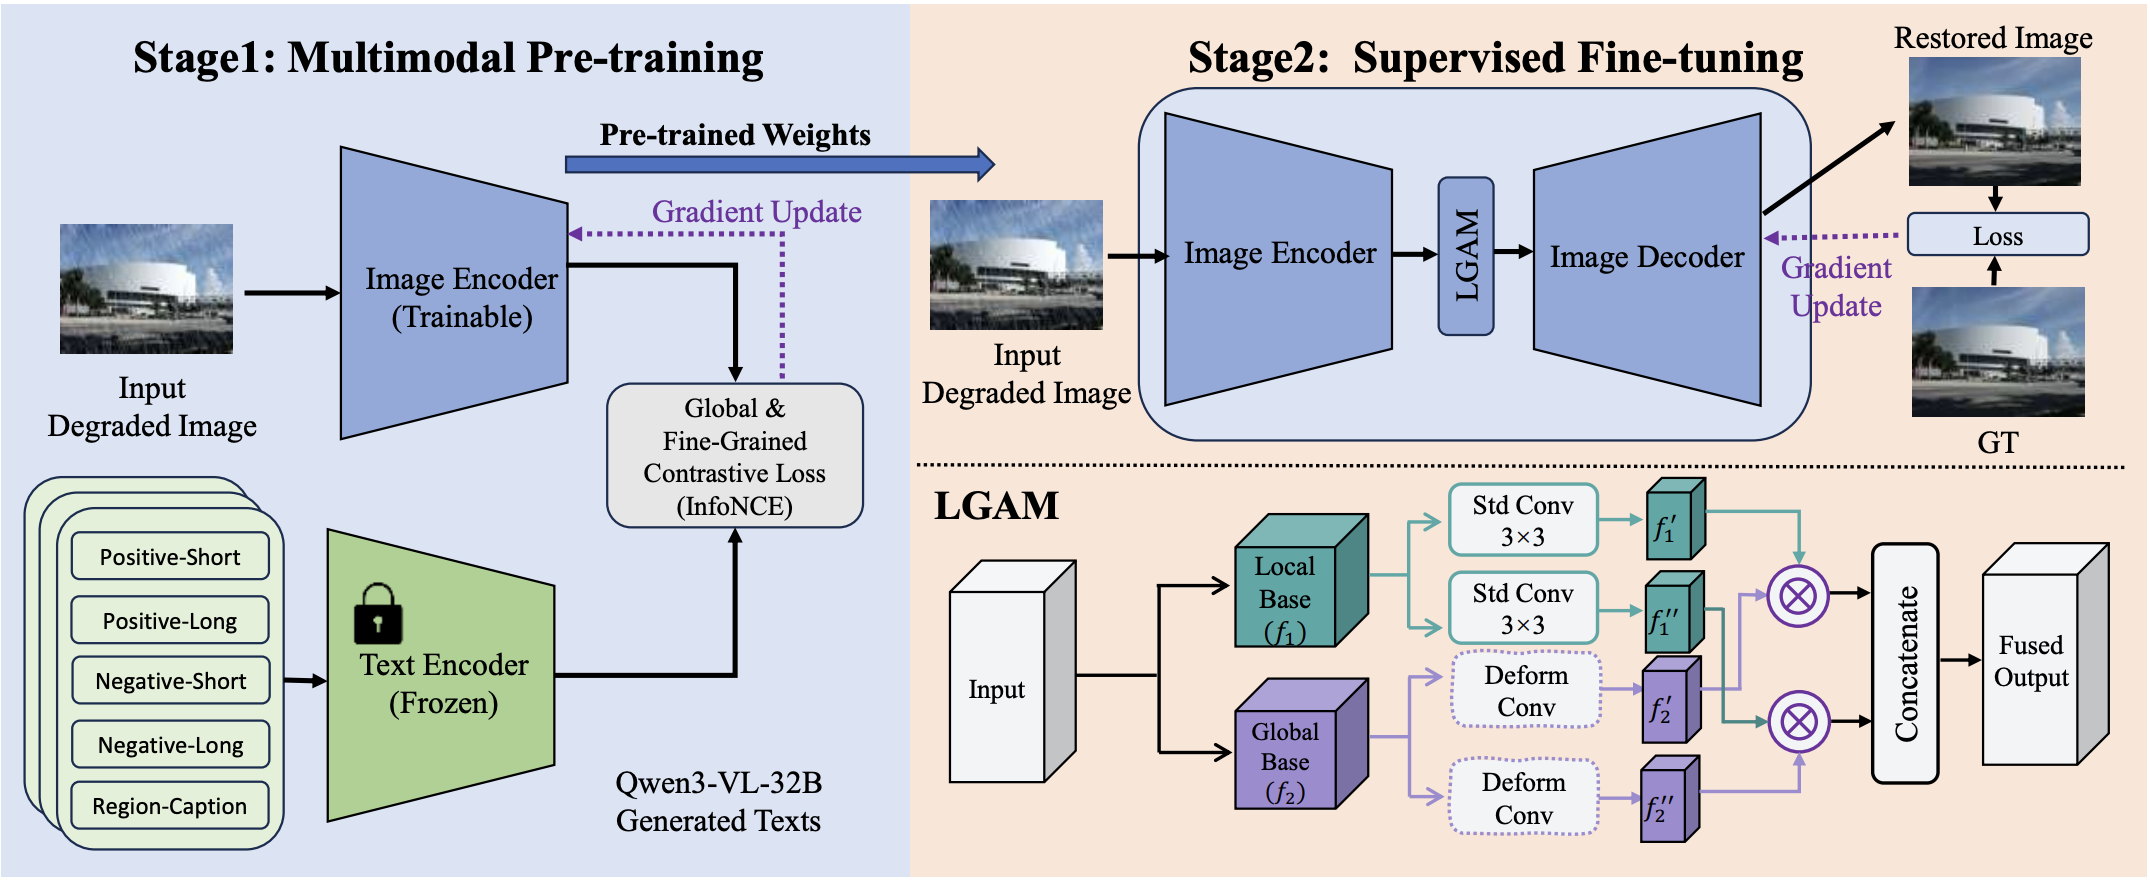 SIGMA: Semantic-Informed Grounded Multimodal Alignment for Image RestorationHaoran Yin*, Chenyu Zhou*, and Yuhua JinIn Proceedings of the 34th ACM International Conference on Multimedia, 2026The co-first authors are listed in alphabetical order.
Image restoration aims to recover clean, high-fidelity images from degraded inputs. However, existing vision-only methods lack explicit semantic context, often struggling to distinguish degradation artifacts from intrinsic image textures. While recent multimodal approaches introduce language guidance, they typically rely on coarse holistic descriptions and positive-only supervision, which limits fine-grained semantic alignment under severe degradations. To overcome these limitations, we introduce the Unified Multimodal Restoration 1-Million (UMR-1M) dataset, a large-scale multimodal dataset tailored for low-level image restoration. UMR-1M goes beyond standard positive captions by incorporating hallucinated hard negatives and fine-grained region grounding, enabling more discriminative cross-modal alignment. Built on this foundation, we propose Language-Guided Restoration Alignment Pre-training (LG-RAP), which distills grounded multimodal priors into the visual backbone. Furthermore, we present Semantic-Informed Grounded Multimodal Alignment (SIGMA), a CNN-ViT hybrid restoration framework built upon this alignment paradigm for high-fidelity pixel-wise reconstruction. Extensive experiments on deraining, desnowing, denoising, and deblurring benchmarks demonstrate that SIGMA achieves competitive performance across multiple restoration tasks.
Formatted citationYin, H., Zhou, C., and Jin, Y. SIGMA: Semantic-Informed Grounded Multimodal Alignment for Image Restoration. In Proceedings of the 34th ACM International Conference on Multimedia (MM '26), 2026.
BibTeX@inproceedings{yin2026sigma, title={{SIGMA}: Semantic-Informed Grounded Multimodal Alignment for Image Restoration}, author={Haoran Yin and Chenyu Zhou and Yuhua Jin}, booktitle={Proceedings of the 34th ACM International Conference on Multimedia}, series={MM '26}, year={2026}, publisher={ACM} } - Preprint
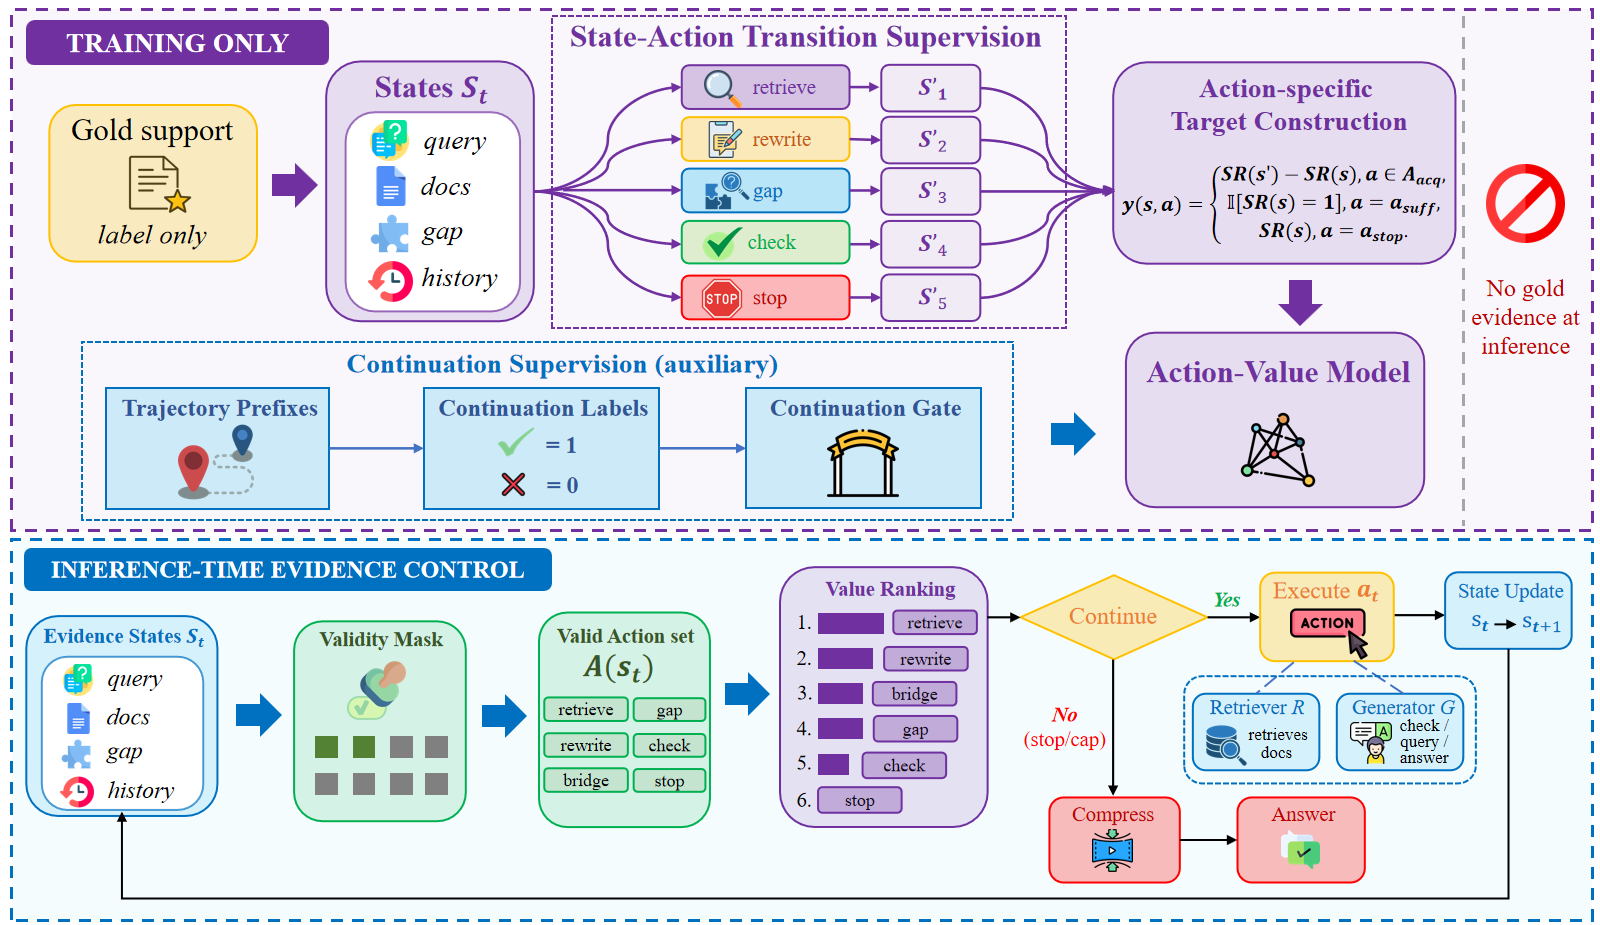 DynaKRAG: A Unified Framework for Learnable Evidence Control in Multi-Hop Retrieval-Augmented GenerationChenyu Zhou, Yaqi Wu, Xiaolei Guo, Jiaqi Huang, Xianfa Zhang, Junxu Zhang, Zhuo Yu, Zhubo Shi, Jianghao Lin, and Dongdong GearXiv preprint arXiv:2607.06507, 2026
Multi-hop retrieval-augmented generation (RAG) acquires evidence sequentially, with each new document potentially revealing missing facts, bridge entities, query defects, or sufficient support for answering. Existing methods provide useful operations such as iterative retrieval, query reformulation, evidence critique, and sufficiency judging, but typically organize them within method-specific pipelines or predefined control topologies. This leaves underexplored how to learn a shared state-conditioned policy that chooses among currently valid evidence operations. We introduce DynaKRAG, which formulates multi-hop evidence acquisition as state-conditioned control over atomic evidence operations. At each step, a validity layer constructs the executable action set, and a learned controller selects the next operation. The resulting transition updates the evidence state and may enable new operations at subsequent steps. With Qwen2.5-7B-Instruct, DynaKRAG achieves F1 scores of 0.5998 on HotpotQA, 0.5340 on 2Wiki, and 0.3061 on MuSiQue, outperforming the strongest controlled baseline on all three benchmarks. Replacing the learned controller with a uniform-valid policy reduces F1 by 3.96–5.78 points, while removing sufficiency feedback hurts all three datasets. Controlled retrieval-cap experiments further show that additional retrieval is not uniformly beneficial. Together, these results demonstrate the benefit of coordinating retrieval, diagnosis, and gap-directed acquisition under an evolving evidence state.
Formatted citationZhou, C., Wu, Y., Guo, X., Huang, J., Zhang, X., Zhang, J., Yu, Z., Shi, Z., Lin, J., and Ge, D. DynaKRAG: A Unified Framework for Learnable Evidence Control in Multi-Hop Retrieval-Augmented Generation. arXiv preprint arXiv:2607.06507, 2026.
BibTeX@misc{zhou2026dynakragunifiedframeworklearnable, title={DynaKRAG: A Unified Framework for Learnable Evidence Control in Multi-Hop Retrieval-Augmented Generation}, author={Chenyu Zhou and Yaqi Wu and Xiaolei Guo and Jiaqi Huang and Xianfa Zhang and Junxu Zhang and Zhuo Yu and Zhubo Shi and Jianghao Lin and Dongdong Ge}, year={2026}, eprint={2607.06507}, archivePrefix={arXiv}, primaryClass={cs.CL}, url={https://arxiv.org/abs/2607.06507} } - Preprint
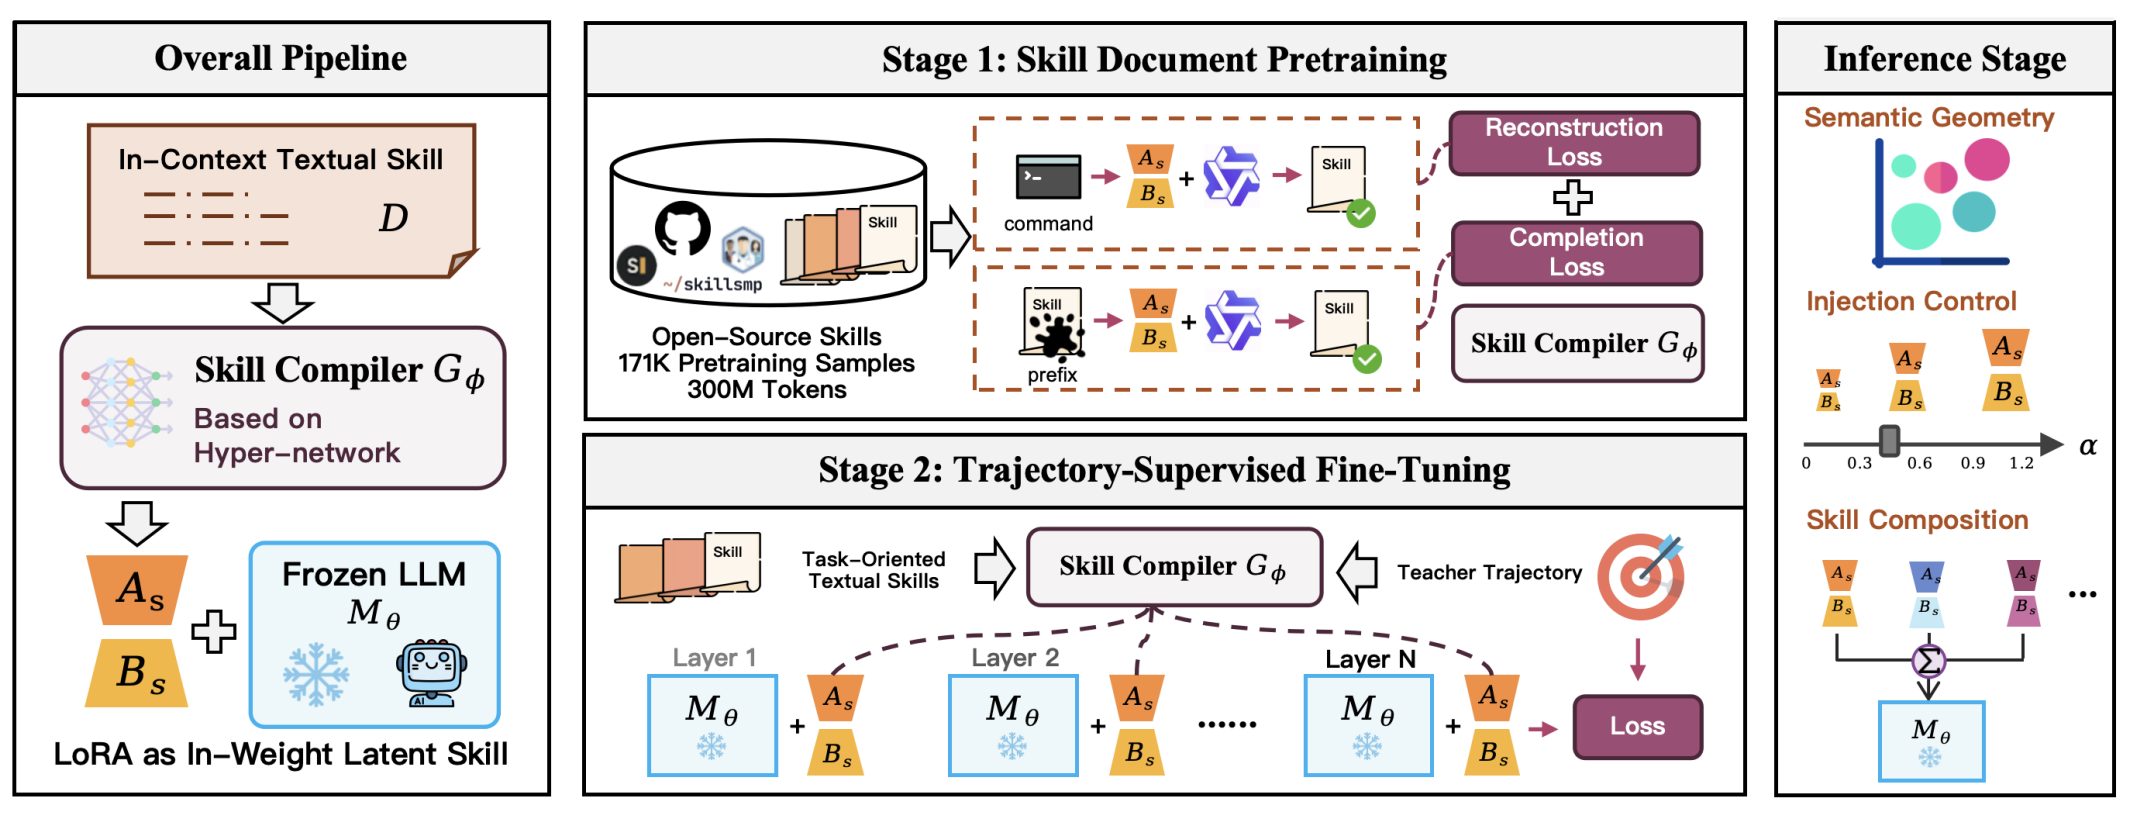 LatentSkill: From In-Context Textual Skills to In-Weight Latent Skills for LLM AgentsAofan Yu*, Chenyu Zhou*, Tianyi Xu, Zihan Guo, Rong Shan, Zhihui Fu, Jun Wang, Weiwen Liu, Yong Yu, Weinan Zhang, and Jianghao LinarXiv preprint arXiv:2606.06087, 2026
Agent systems increasingly use textual skills to encode reusable task procedures, but injecting these skills into the prompt at every step incurs substantial context overhead and exposes skill content as plaintext. We present LatentSkill, a framework that converts textual skills into plug-and-play LoRA adapters through a pretrained hypernetwork. LatentSkill stores skill knowledge in weight space rather than context space, removing per-step skill tokens while preserving modular loading, scaling, and composition. On ALFWorld and Search-QA, LatentSkill outperforms the corresponding in-context skill baseline while using substantially fewer prefill tokens: it improves ALFWorld success by 21.4 and 13.4 points on the seen and unseen splits with 63.9% fewer prefill tokens on average, and improves Search-QA exact match by 3.0 points while using 71.8% fewer tokens per step. Further analysis shows that generated skill LoRAs form a structured semantic geometry, can be continuously modulated via the LoRA scaling coefficient, and can be composed through parameter-space arithmetic when skill components are aligned. These findings suggest that weight-space skills provide an efficient, modular, and less exposed substrate for extending LLM agents.
Formatted citationYu, A., Zhou, C., Xu, T., Guo, Z., Shan, R., Fu, Z., Wang, J., Liu, W., Yu, Y., Zhang, W., and Lin, J. LatentSkill: From In-Context Textual Skills to In-Weight Latent Skills for LLM Agents. arXiv preprint arXiv:2606.06087, 2026.
BibTeX@misc{yu2026latentskillincontexttextualskills, title={LatentSkill: From In-Context Textual Skills to In-Weight Latent Skills for LLM Agents}, author={Aofan Yu and Chenyu Zhou and Tianyi Xu and Zihan Guo and Rong Shan and Zhihui Fu and Jun Wang and Weiwen Liu and Yong Yu and Weinan Zhang and Jianghao Lin}, year={2026}, eprint={2606.06087}, archivePrefix={arXiv}, primaryClass={cs.CL}, url={https://arxiv.org/abs/2606.06087} } - Preprint
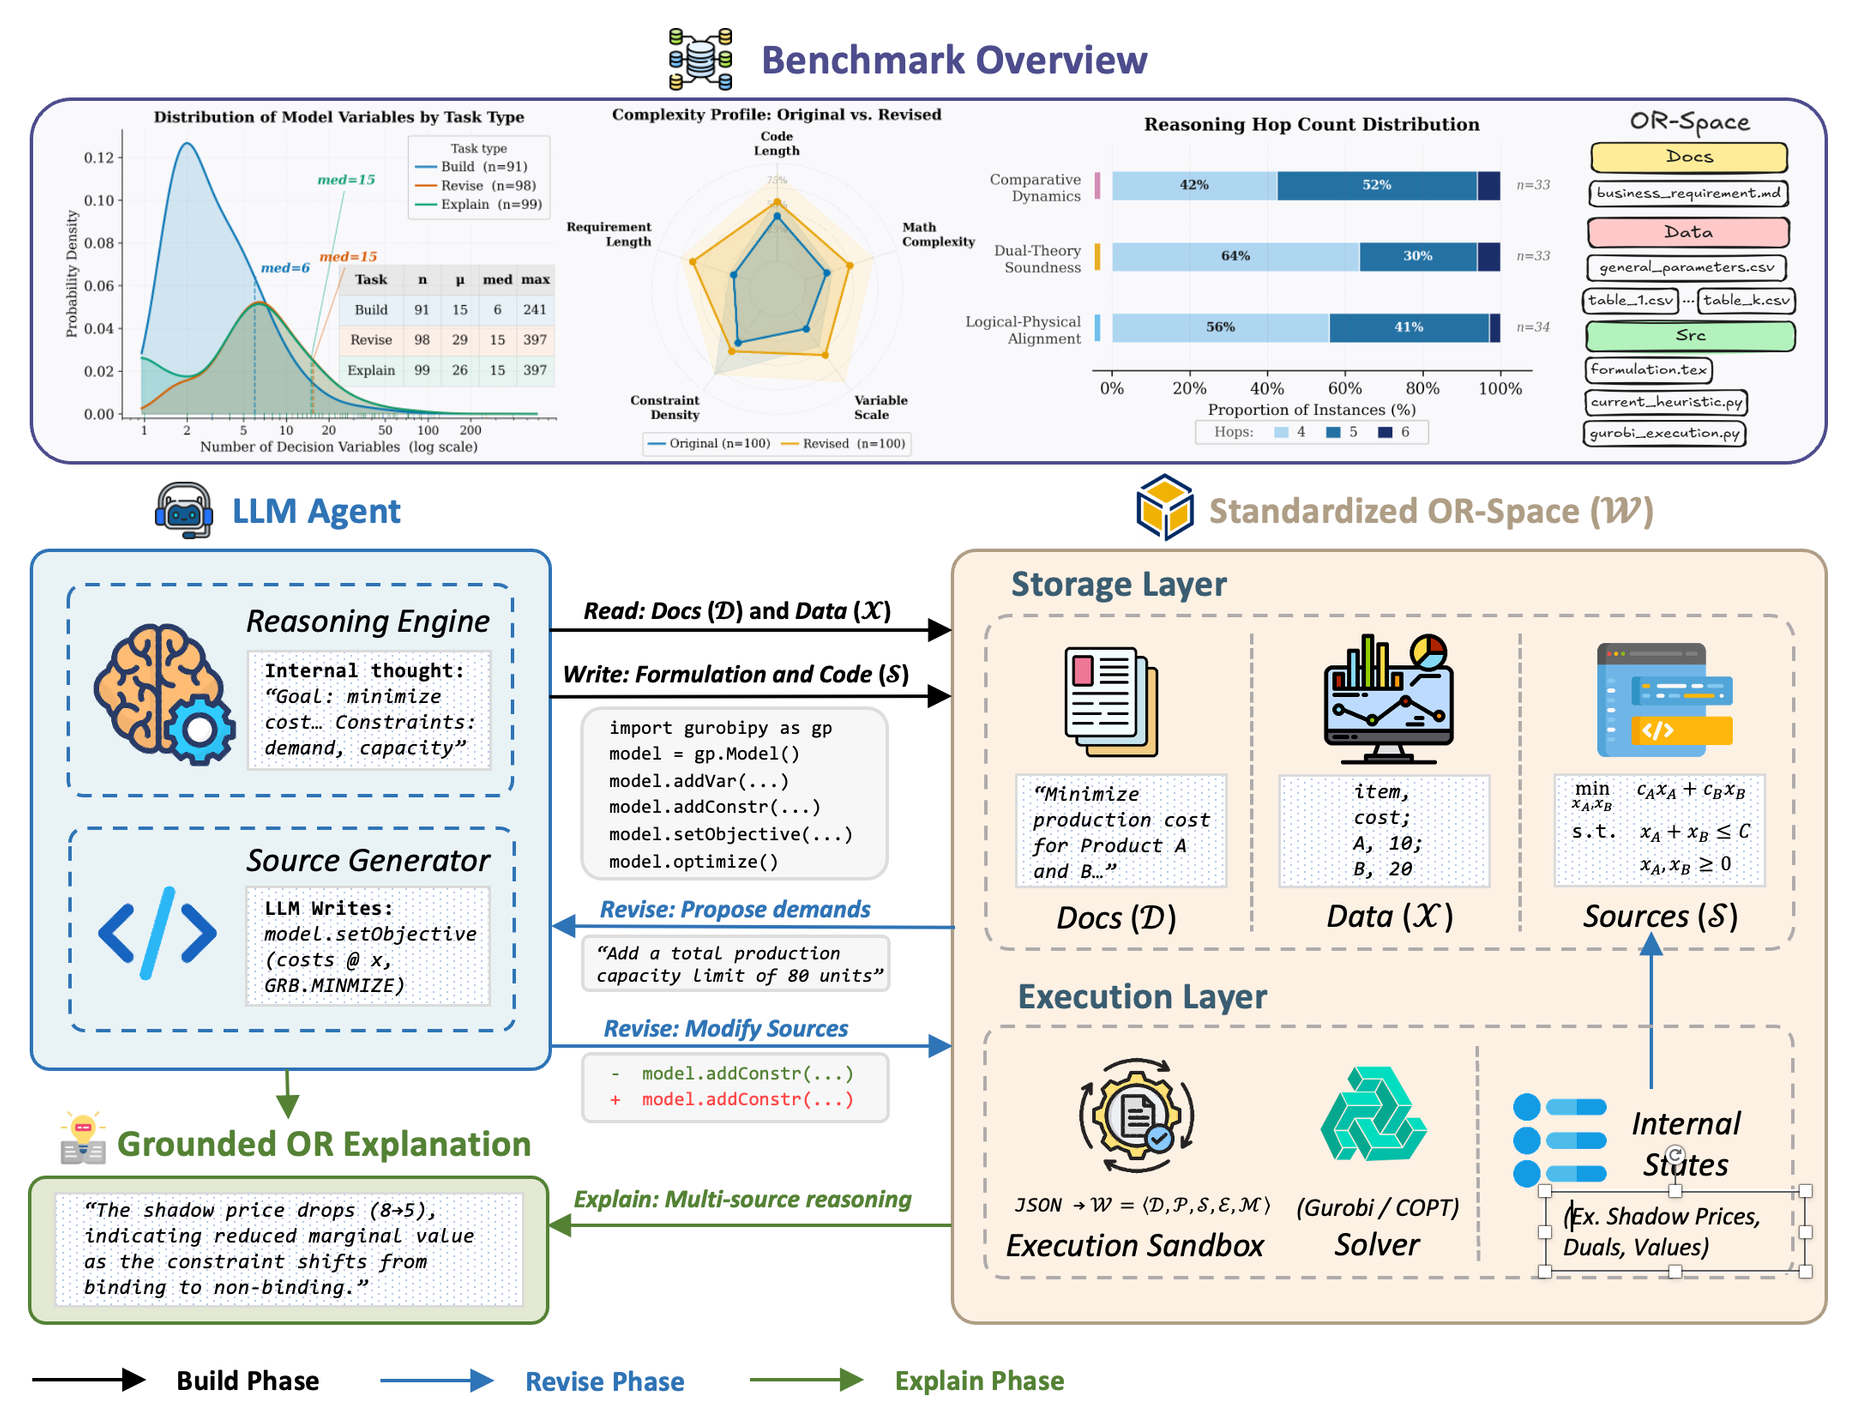 OR-Space: A Full-Lifecycle Workspace Benchmark for Industrial Optimization AgentsarXiv preprint arXiv:2605.28158, 2026
Large language model agents are increasingly used to assist with operations research modeling, yet existing OR-oriented benchmarks often reduce evaluation to one-shot translation from a self-contained textual problem statement into a mathematical formulation or solver program. OR-Space is a full-lifecycle workspace benchmark for evaluating industrial optimization agents across model construction, model revision, and grounded explanation. Each instance is represented as a persistent executable workspace containing business documents, structured data, optional code artifacts, solver outputs, and task-specific evaluators distributed across multiple interdependent files. By combining persistent multi-artifact workspaces with lifecycle-oriented task modes, OR-Space evaluates whether agents can perform reliable optimization work beyond end-to-end text generation.
Formatted citationZhou, C., Lu, X., Zhao, J., Lin, J., Ge, D., and Ye, Y. OR-Space: A Full-Lifecycle Workspace Benchmark for Industrial Optimization Agents. arXiv preprint arXiv:2605.28158, 2026.
BibTeX@misc{zhou2026orspacefulllifecycleworkspacebenchmark, title={OR-Space: A Full-Lifecycle Workspace Benchmark for Industrial Optimization Agents}, author={Chenyu Zhou and Xinyun Lu and Jiangyue Zhao and Jianghao Lin and Dongdong Ge and Yinyu Ye}, year={2026}, eprint={2605.28158}, archivePrefix={arXiv}, primaryClass={cs.AI}, url={https://arxiv.org/abs/2605.28158} } - Preprint
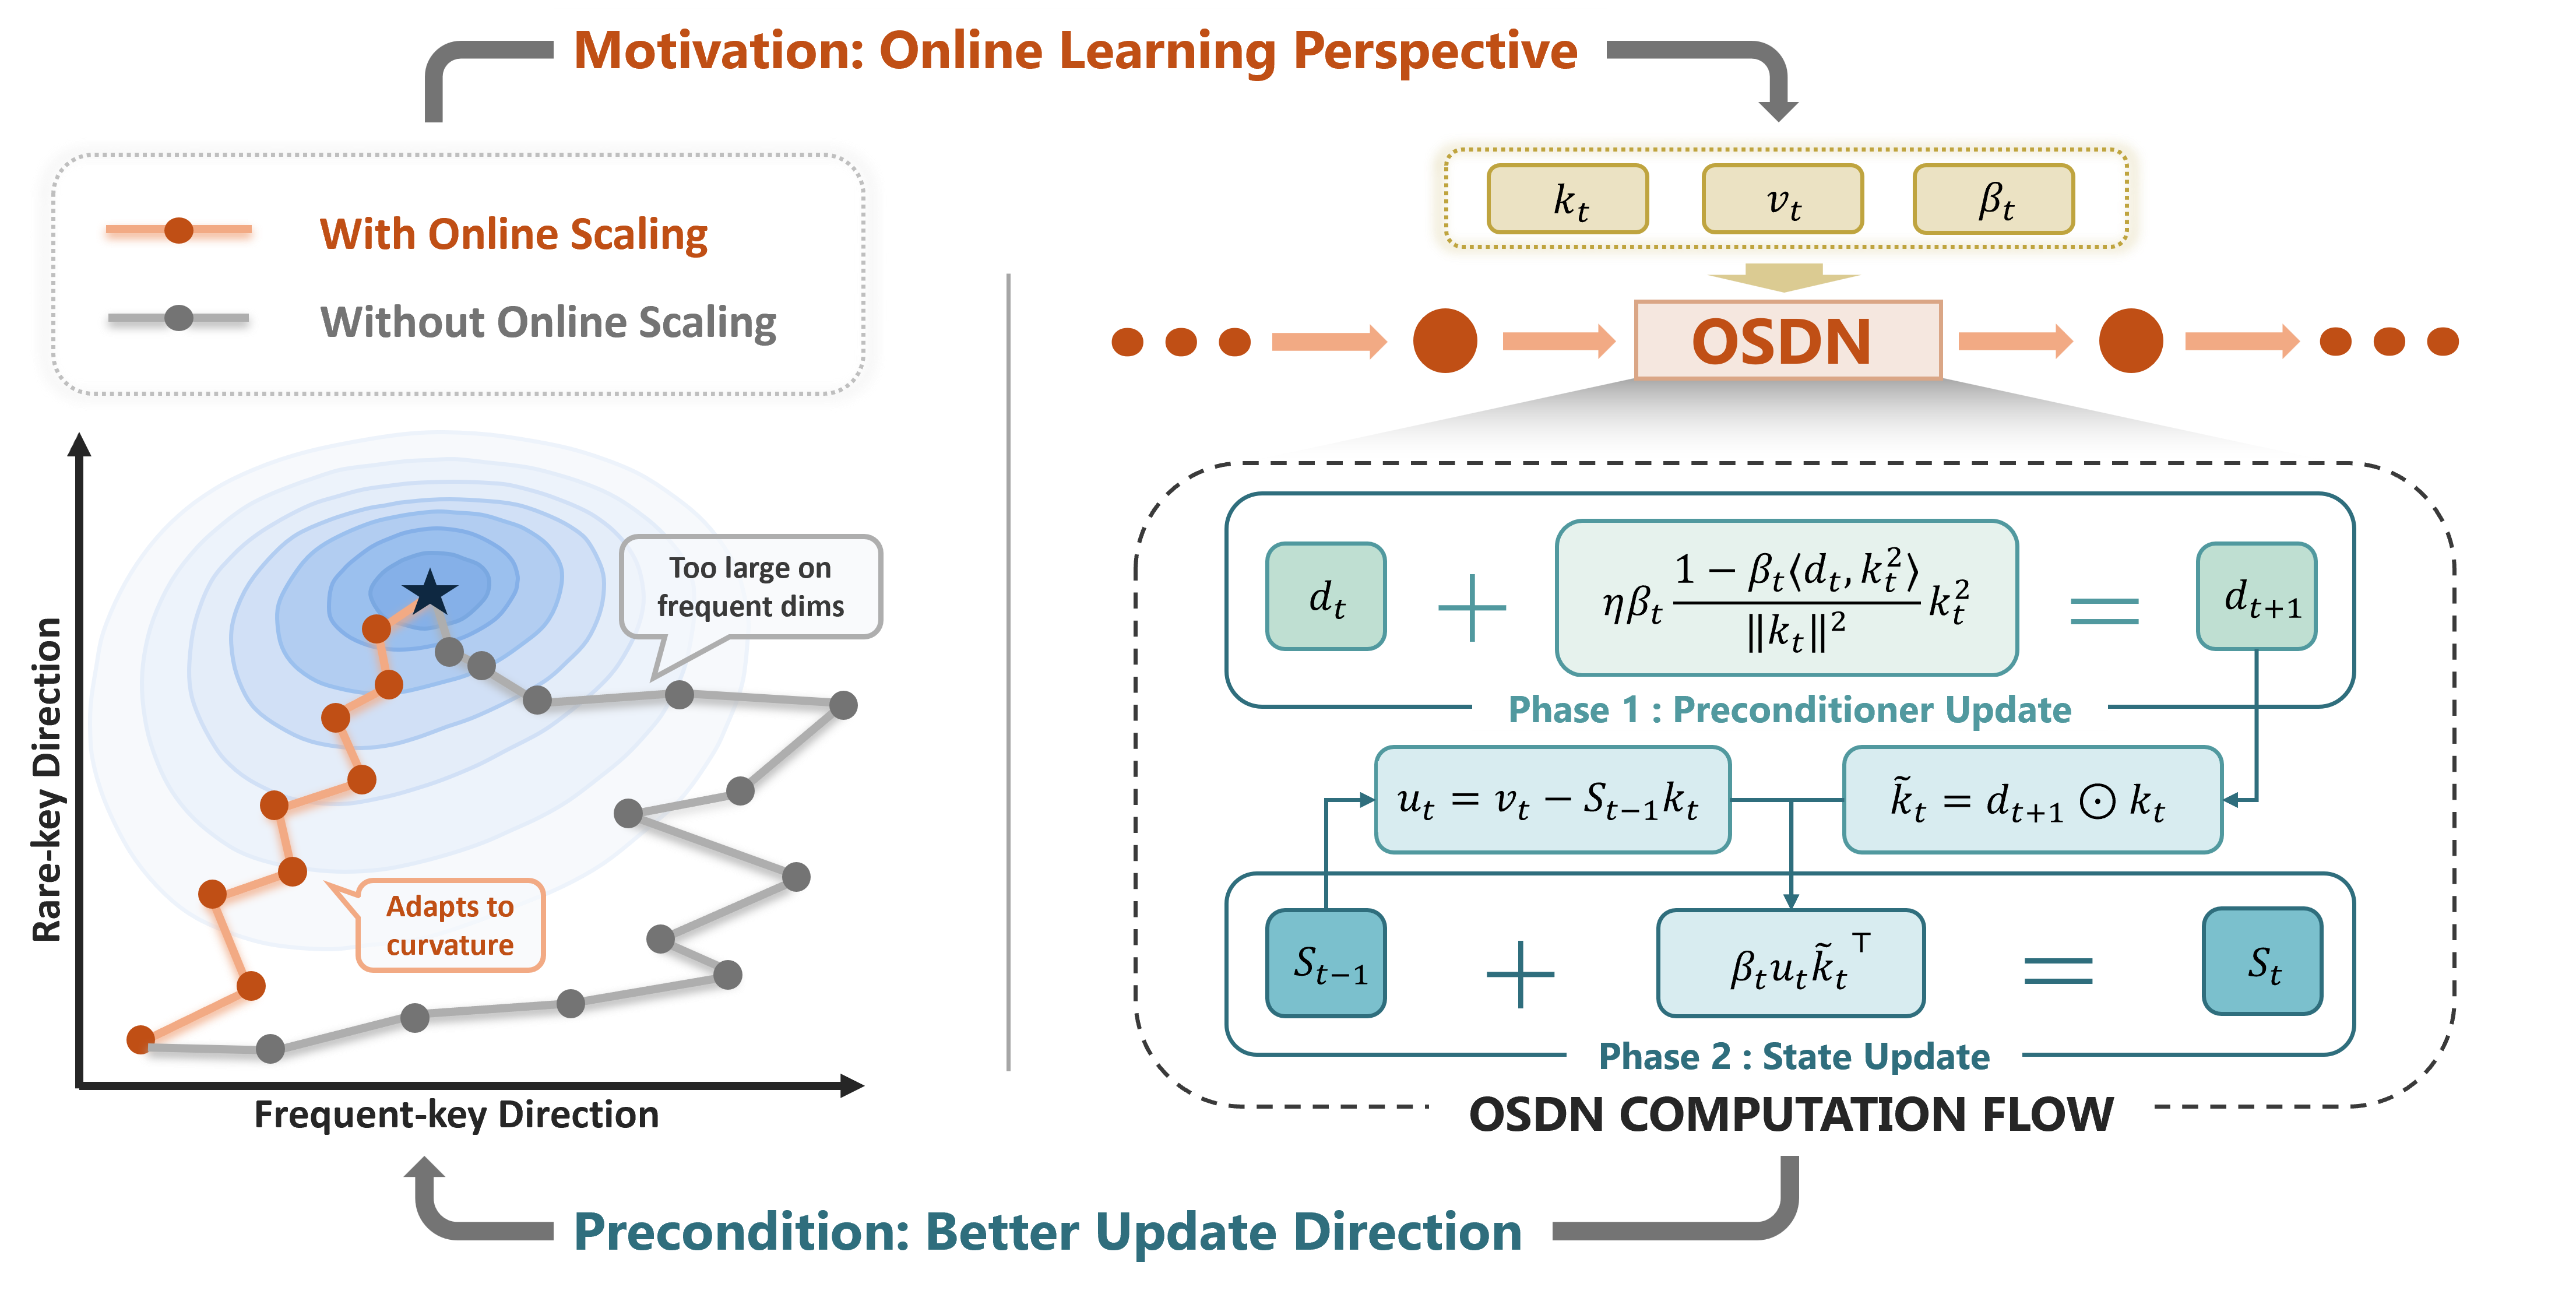 OSDN: Improving Delta Rule with Provable Online Preconditioning in Linear AttentionarXiv preprint arXiv:2605.13473, 2026
Linear attention and state-space models offer constant-memory alternatives to softmax attention, but often struggle with in-context associative recall. The Delta Rule mitigates this by writing each token via one step of online gradient descent. However, its step size relies on a single scalar gate that ignores the feature-wise curvature of the inner objective. We propose Online Scaled DeltaNet (OSDN), which augments the scalar gate with a diagonal preconditioner updated online via hypergradient feedback. Crucially, this right-preconditioning is algebraically equivalent to a per-feature scaling of the write-side key. This equivalence allows OSDN to strictly preserve the hardware-friendly chunkwise parallel pipeline of DeltaNet without incurring high-dimensional state overhead. Theoretically, by exploiting the exact-quadratic structure of the inner regression loss, we establish super-geometric convergence against a right-Newton comparator and prove an algorithm-aligned token-local residual contraction bound. To handle non-stationary contexts, we further introduce Adaptive Preconditioner Forgetting (APF) to dynamically refresh stale calibration. Empirically, OSDN demonstrates strong performance across scales. At the 340M-parameter scale, OSDN improves JRT-style in-context recall by 32% over DeltaNet. Scaling to 1.3B parameters, it achieves a 39% reduction in the recall residual ratio while maintaining parity on general downstream tasks, demonstrating that our online-preconditioning mechanism effectively transfers and amplifies at the billion-parameter scale.
Formatted citationZhou, C., Li, H., Liu, Y., Lin, J., Ge, D., and Ye, Y. OSDN: Improving Delta Rule with Provable Online Preconditioning in Linear Attention. arXiv preprint arXiv:2605.13473, 2026.
BibTeX@misc{zhou2026osdnimprovingdeltarule, title={OSDN: Improving Delta Rule with Provable Online Preconditioning in Linear Attention}, author={Chenyu Zhou and Hongpei Li and Yuerou Liu and Jianghao Lin and Dongdong Ge and Yinyu Ye}, year={2026}, eprint={2605.13473}, archivePrefix={arXiv}, primaryClass={cs.LG}, url={https://arxiv.org/abs/2605.13473} } - Preprint
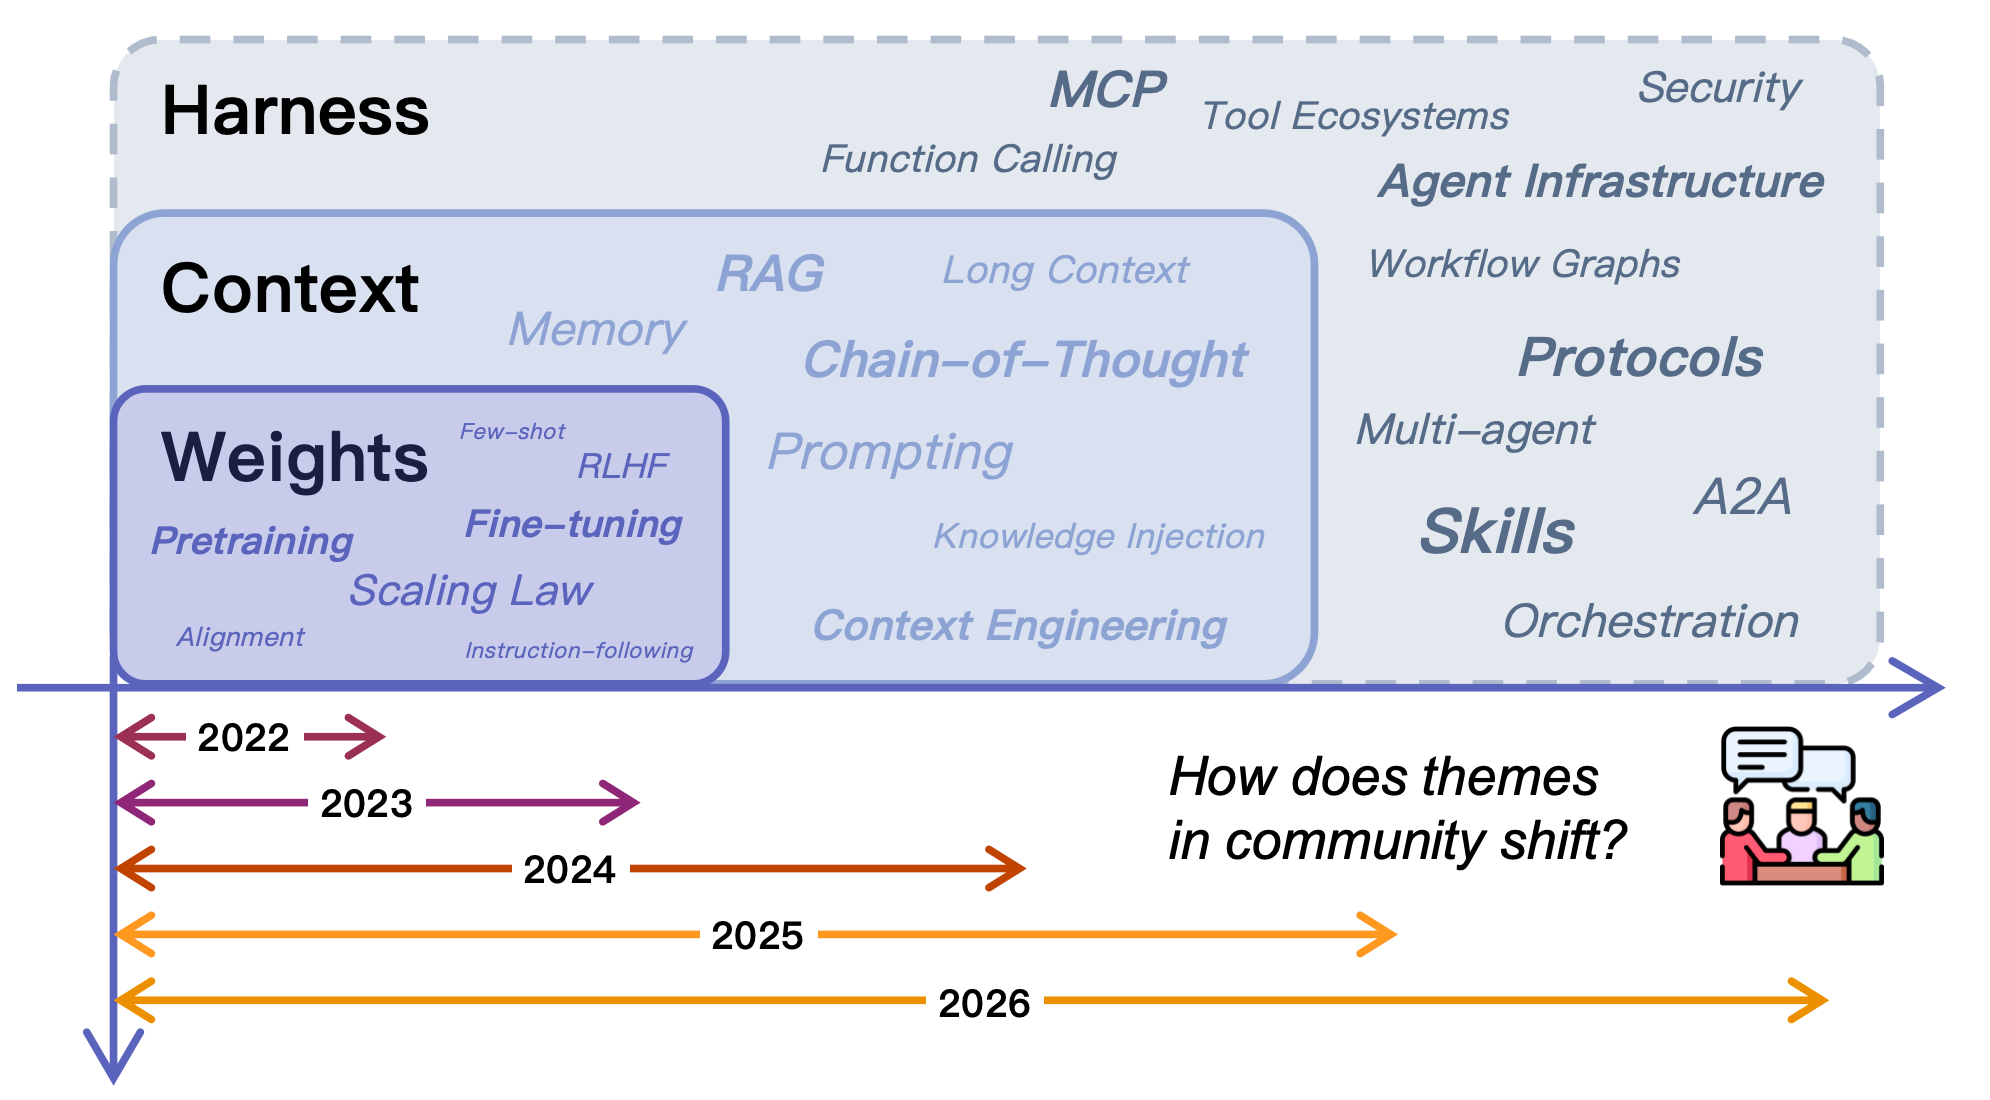 Externalization in LLM Agents: A Unified Review of Memory, Skills, Protocols and Harness EngineeringChenyu Zhou, Huacan Chai*, Wenteng Chen*, Zihan Guo*, Rong Shan*, Yuanyi Song*, Tianyi Xu*, Yingxuan Yang*, Aofan Yu*, Weiming Zhang*, Congming Zheng*, Jiachen Zhu*, Zeyu Zheng, Zhuosheng Zhang, Xingyu Lou, Changwang Zhang, Zhihui Fu, Jun Wang, Weiwen Liu, Jianghao Lin, and Weinan ZhangarXiv preprint arXiv:2604.08224, 2026
LLM agent development increasingly relies on reorganizing runtime infrastructure rather than modifying model weights. We present a framework analyzing four externalization dimensions: memory stores persist state over time, skills encapsulate procedural knowledge, protocols structure interactions, and harness engineering coordinates these elements into reliable execution. We trace progress from weights to context to harness design, examining trade-offs between parametric and externalized capabilities while discussing evaluation challenges and the co-evolution of models with external infrastructure.
Formatted citationZhou, C., Chai, H., Chen, W., Guo, Z., Shan, R., Song, Y., Xu, T., Yang, Y., Yu, A., Zhang, W., Zheng, C., Zhu, J., Zheng, Z., Zhang, Z., Lou, X., Zhang, C., Fu, Z., Wang, J., Liu, W., Lin, J., and Zhang, W. Externalization in LLM Agents: A Unified Review of Memory, Skills, Protocols and Harness Engineering. arXiv preprint arXiv:2604.08224, 2026.
BibTeX@misc{zhou2026externalizationllmagentsunified, title={Externalization in LLM Agents: A Unified Review of Memory, Skills, Protocols and Harness Engineering}, author={Chenyu Zhou and Huacan Chai and Wenteng Chen and Zihan Guo and Rong Shan and Yuanyi Song and Tianyi Xu and Yingxuan Yang and Aofan Yu and Weiming Zhang and Congming Zheng and Jiachen Zhu and Zeyu Zheng and Zhuosheng Zhang and Xingyu Lou and Changwang Zhang and Zhihui Fu and Jun Wang and Weiwen Liu and Jianghao Lin and Weinan Zhang}, year={2026}, eprint={2604.08224}, archivePrefix={arXiv}, primaryClass={cs.SE}, url={https://arxiv.org/abs/2604.08224} } - ICLR 2026
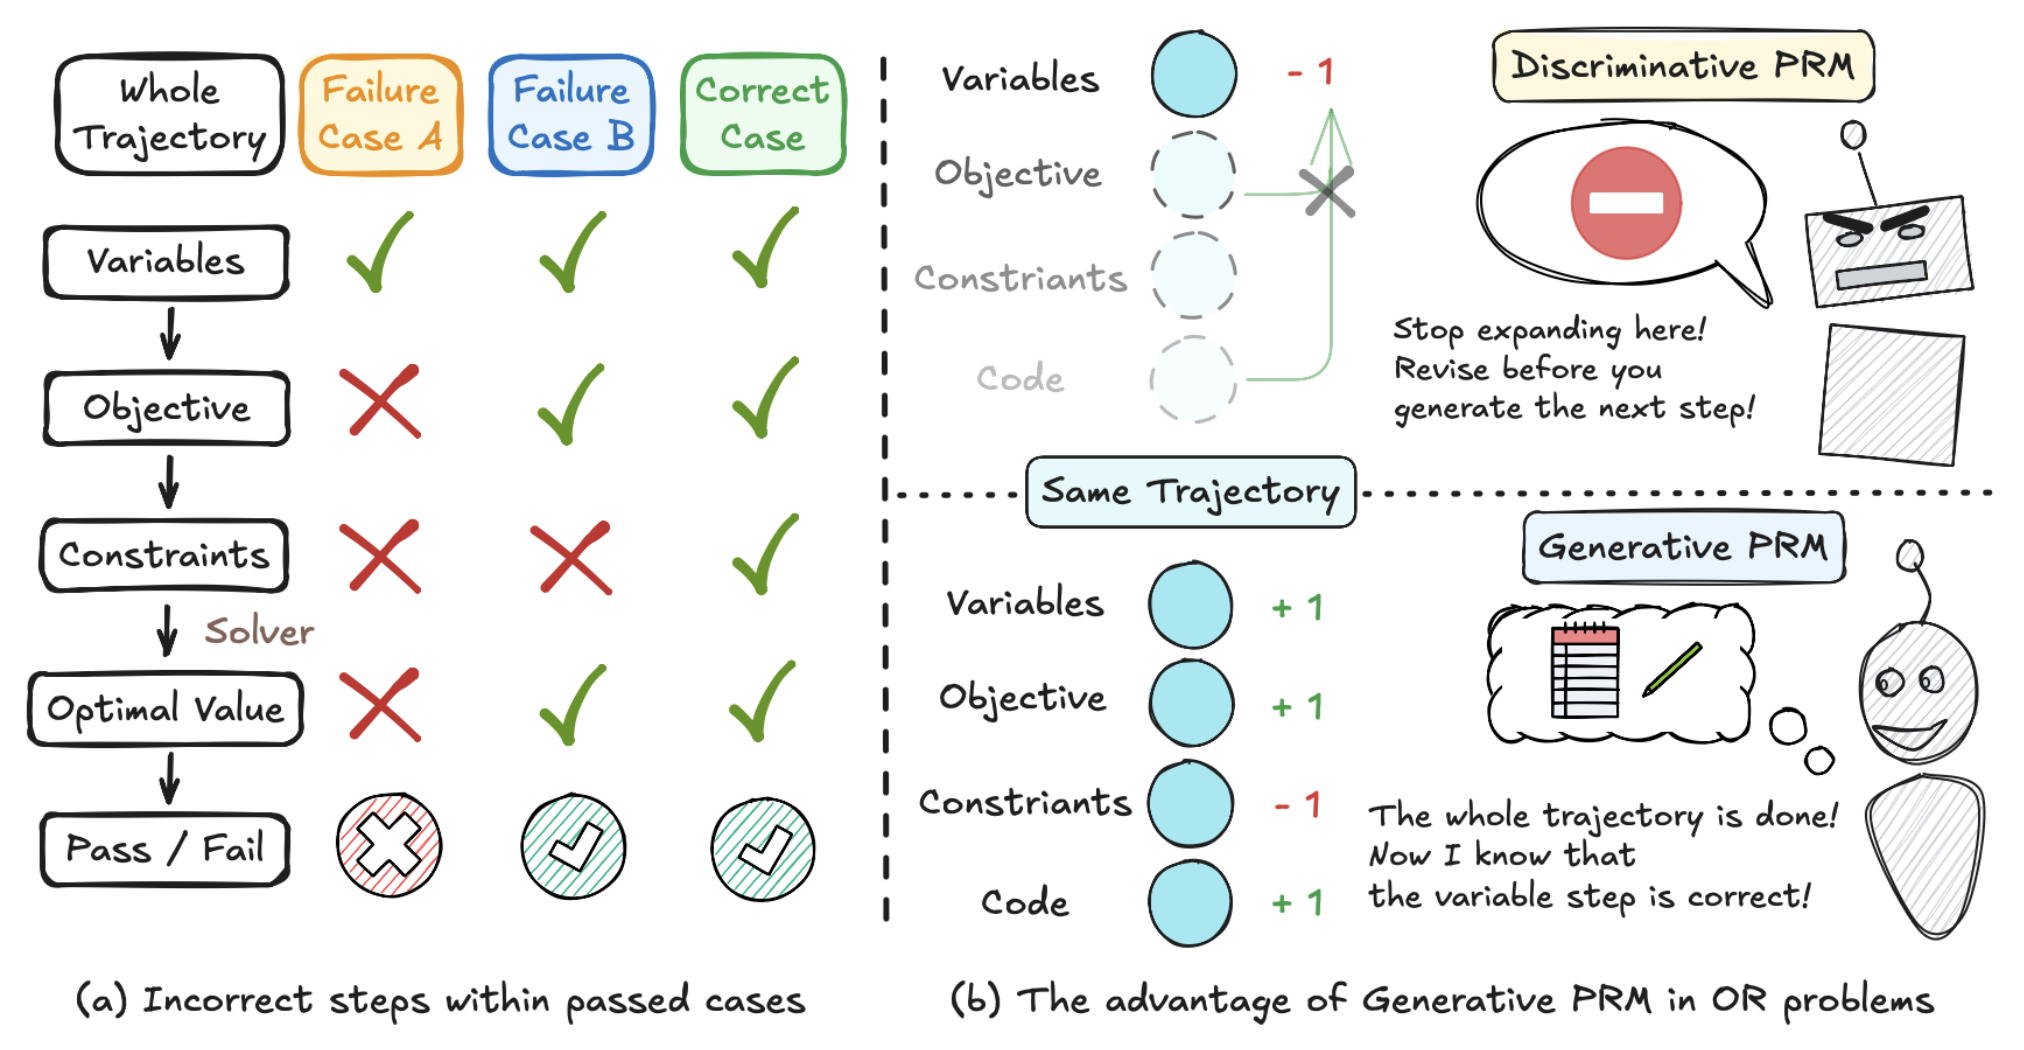 StepORLM: A Self-Evolving Framework With Generative Process Supervision For Operations Research Language ModelsChenyu Zhou, Tianyi Xu, Jianghao Lin, and Dongdong GeThe Fourteenth International Conference on Learning Representations, 2026
Large Language Models (LLMs) have shown promising capabilities for solving Operations Research (OR) problems. While reinforcement learning serves as a powerful paradigm for LLM training on OR problems, existing works generally face two key limitations. First, outcome reward suffers from the credit assignment problem, where correct final answers can reinforce flawed reasoning. Second, conventional discriminative process supervision is myopic, failing to evaluate the interdependent steps of OR modeling holistically. To this end, we introduce StepORLM, a novel self-evolving framework with generative process supervision. At its core, StepORLM features a co-evolutionary loop where a policy model and a generative process reward model (GenPRM) iteratively improve on each other. This loop is driven by a dual-feedback mechanism: definitive, outcome-based verification from an external solver, and nuanced, holistic process evaluation from the GenPRM. The combined signal is used to align the policy via Weighted Direct Preference Optimization (W-DPO) and simultaneously refine the GenPRM. Our resulting 8B-parameter StepORLM establishes a new state-of-the-art across six benchmarks, significantly outperforming vastly larger generalist models, agentic methods, and specialized baselines. Moreover, the co-evolved GenPRM is able to act as a powerful and universally applicable process verifier, substantially boosting the inference scaling performance of both our own model and other existing LLMs.
Formatted citationZhou, C., Xu, T., Lin, J., and Ge, D. StepORLM: A Self-Evolving Framework With Generative Process Supervision For Operations Research Language Models. In The Fourteenth International Conference on Learning Representations, 2026.
BibTeX@inproceedings{zhou2026steporlm, title={Step{ORLM}: A Self-Evolving Framework With Generative Process Supervision For Operations Research Language Models}, author={Chenyu Zhou and Tianyi Xu and Jianghao Lin and Dongdong Ge}, booktitle={The Fourteenth International Conference on Learning Representations}, year={2026}, url={https://openreview.net/forum?id=ZrgxU8WMmG} } - Preprint
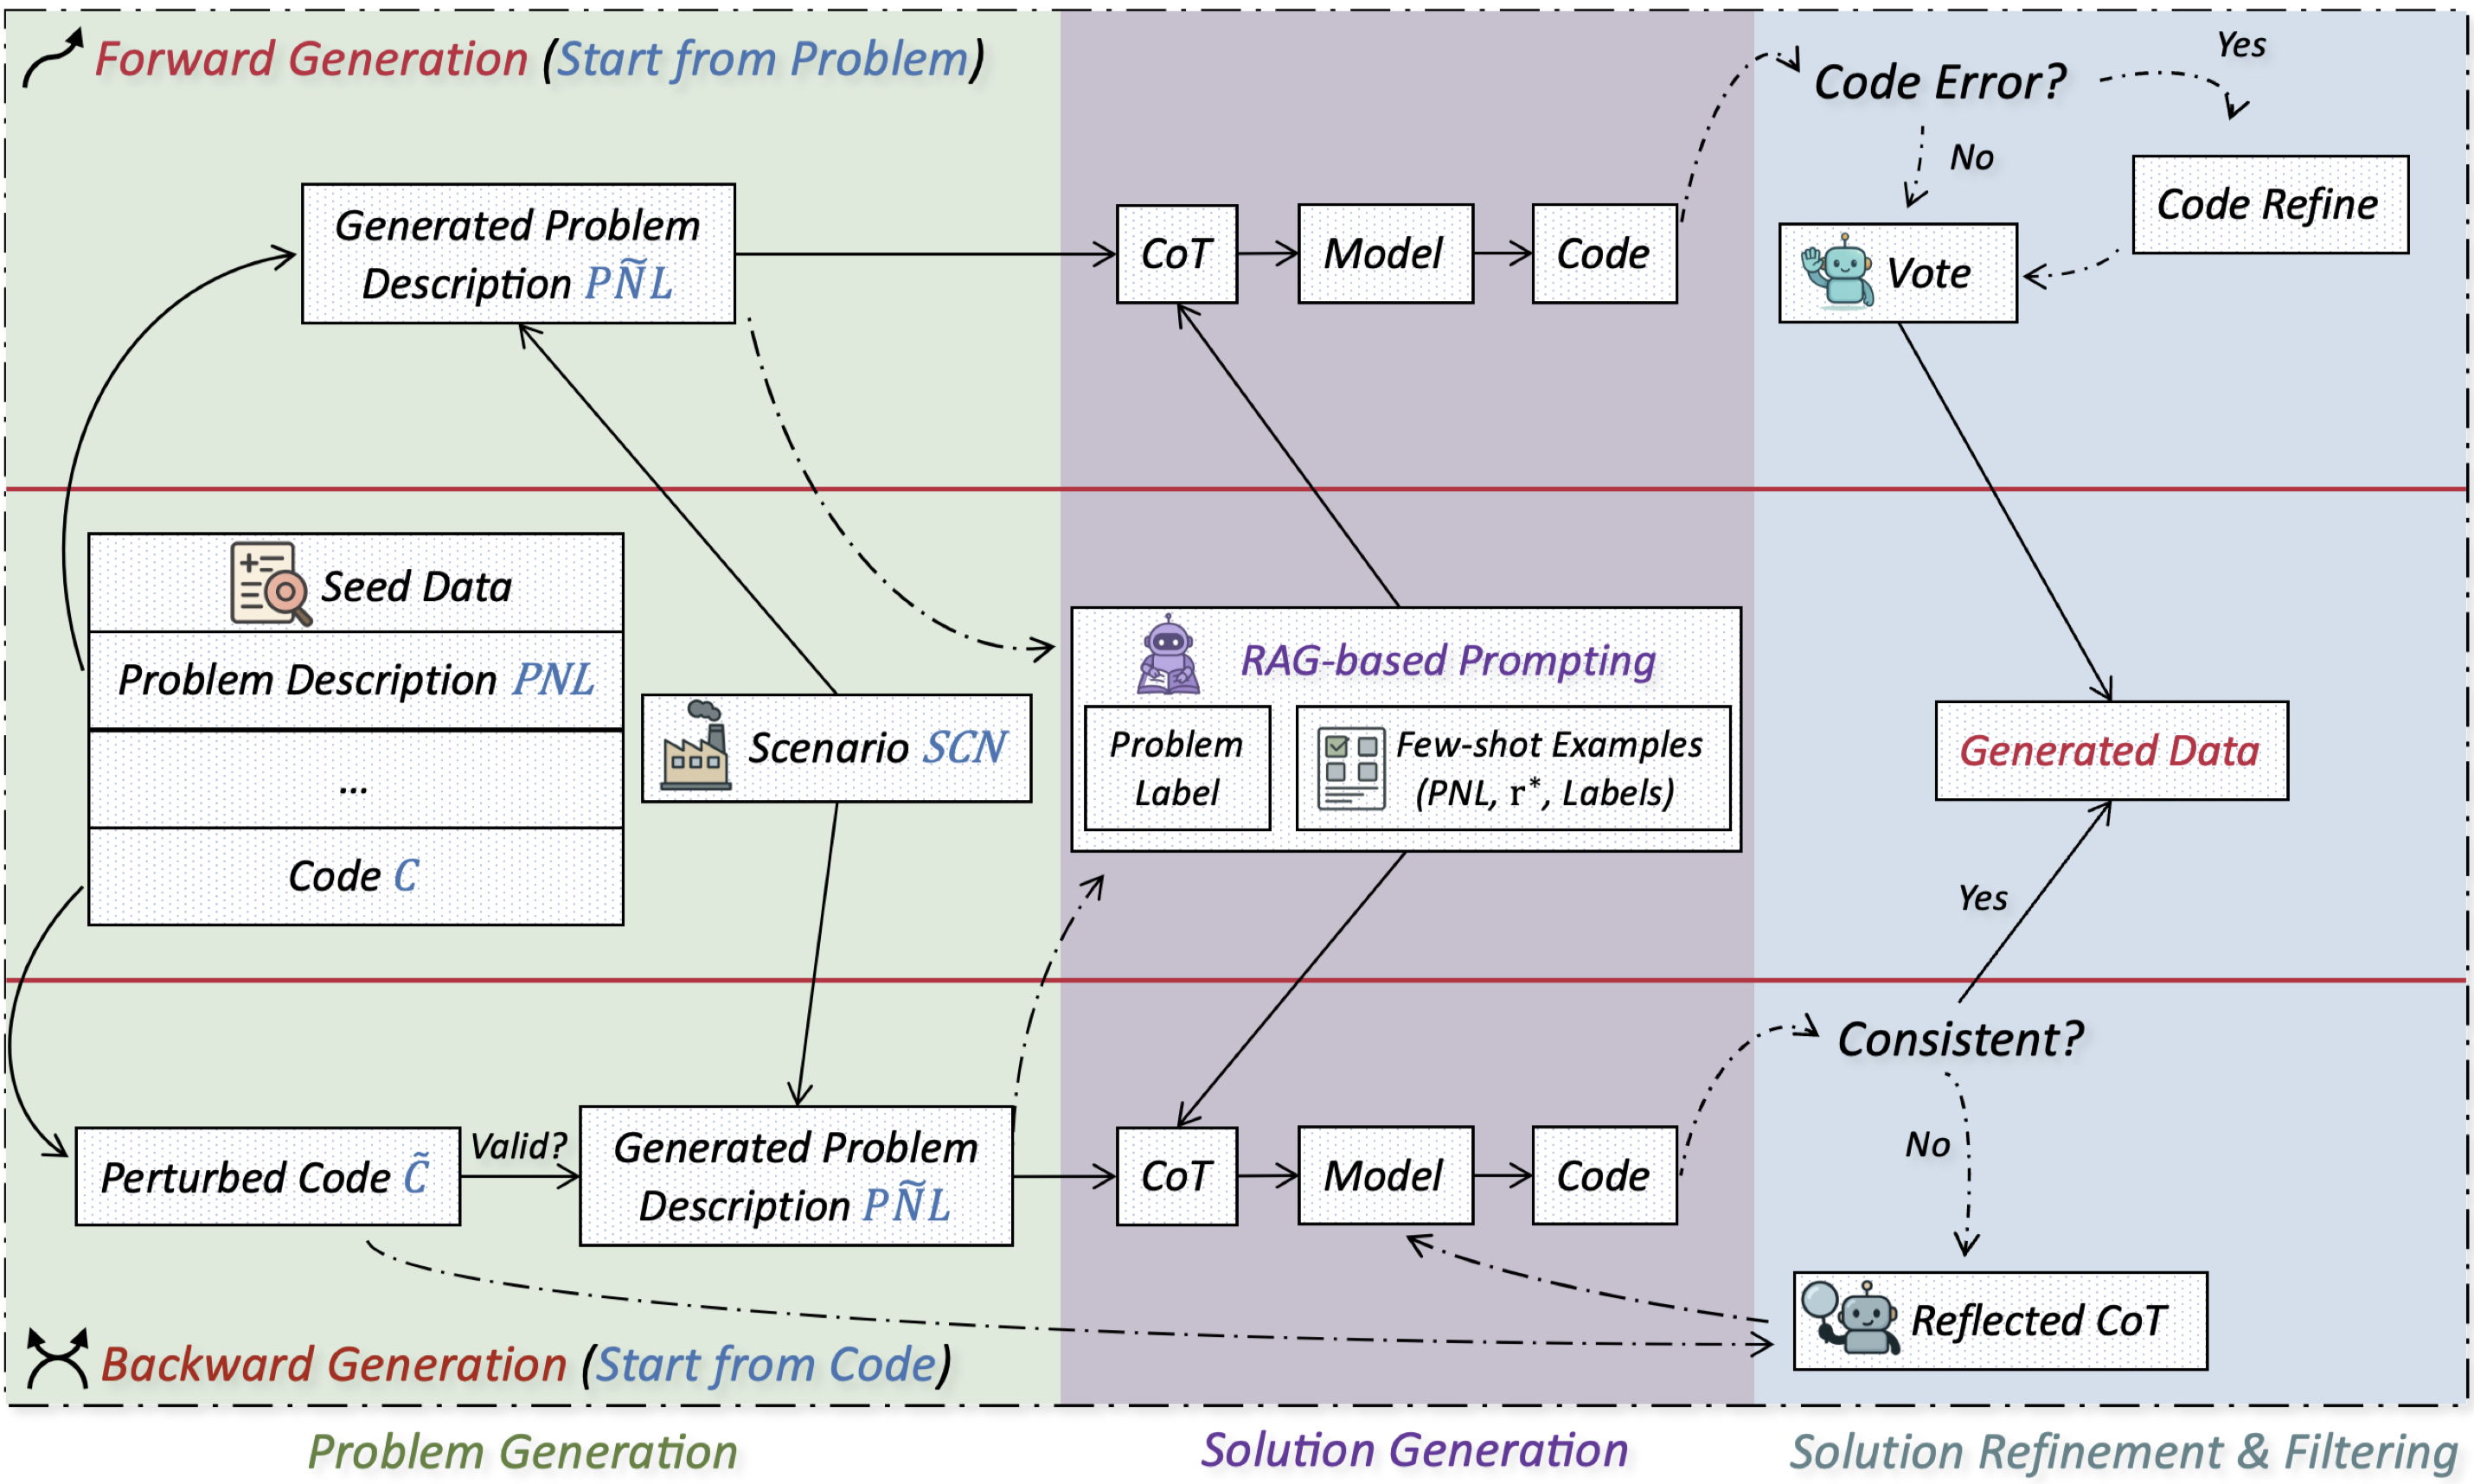 Auto-Formulating Dynamic Programming Problems with Large Language ModelsChenyu Zhou*, Jingyuan Yang*, Linwei Xin, Yitian Chen, Ziyan He, and Dongdong GeMajor Revision at Manufacturing & Service Operations Management, 2025
Dynamic programming (DP) is a fundamental method in operations research, but formulating DP models has traditionally required expert knowledge of both the problem context and DP techniques. Large Language Models (LLMs) offer the potential to automate this process. However, DP problems pose unique challenges due to their inherently stochastic transitions and the limited availability of training data. These factors make it difficult to directly apply existing LLM-based models or frameworks developed for other optimization problems, such as linear or integer programming. We introduce DP-Bench, the first benchmark covering a wide range of textbook-level DP problems to enable systematic evaluation. We present Dynamic Programming Language Model (DPLM), a 7B-parameter specialized model that achieves performance comparable to state-of-the-art LLMs like OpenAI’s o1 and DeepSeek-R1, and surpasses them on hard problems. Central to DPLM’s effectiveness is DualReflect, our novel synthetic data generation pipeline, designed to scale up training data from a limited set of initial examples. DualReflect combines forward generation for diversity and backward generation for reliability. Our results reveal a key insight: backward generation is favored in low-data regimes for its strong correctness guarantees, while forward generation, though lacking such guarantees, becomes increasingly valuable at scale for introducing diverse formulations. This trade-off highlights the complementary strengths of both approaches and the importance of combining them.
Formatted citationZhou, C., Yang, J., Xin, L., Chen, Y., He, Z., and Ge, D. Auto-Formulating Dynamic Programming Problems with Large Language Models. arXiv preprint arXiv:2507.11737, 2026.
BibTeX@misc{zhou2026autoformulatingdynamicprogrammingproblems, title={Auto-Formulating Dynamic Programming Problems with Large Language Models}, author={Chenyu Zhou and Jingyuan Yang and Linwei Xin and Yitian Chen and Ziyan He and Dongdong Ge}, year={2026}, eprint={2507.11737}, archivePrefix={arXiv}, primaryClass={cs.AI}, url={https://arxiv.org/abs/2507.11737} } - WWW 2024
 ARTEMIS: Detecting Airdrop Hunters in NFT Markets with a Graph Learning SystemChenyu Zhou, Hongzhou Chen, Hao Wu, Junyu Zhang, and Wei CaiIn The 2024 ACM Web Conference (Oral)
As Web3 projects leverage airdrops to incentivize participation, airdrop hunters tactically amass wallet addresses to capitalize on token giveaways. This poses challenges to the decentralization goal. Current detection approaches tailored for cryptocurrencies overlook non-fungible tokens (NFTs) nuances. We introduce ARTEMIS, an optimized graph neural network system for identifying airdrop hunters in NFT transactions. ARTEMIS captures NFT airdrop hunters through: (1) a multimodal module extracting visual and textual insights from NFT metadata using Transformer models; (2) a tailored node aggregation function chaining NFT transaction sequences, retaining behavioral insights; (3) engineered features based on market manipulation theories detecting anomalous trading. Evaluated on decentralized exchange Blur’s data, ARTEMIS significantly outperforms baselines in pinpointing hunters. This pioneering computational solution for an emergent Web3 phenomenon has broad applicability for blockchain anomaly detection. The data and code for the paper are accessible at the following link: doi.org/10.5281/zenodo.10676801.
Formatted citationZhou, C., Chen, H., Wu, H., Zhang, J., and Cai, W. ARTEMIS: Detecting Airdrop Hunters in NFT Markets with a Graph Learning System. In Proceedings of the ACM Web Conference 2024 (WWW '24), pp. 1824–1834, 2024. doi:10.1145/3589334.3645597.
BibTeX@inproceedings{zhou2024artemis, title={{ARTEMIS}: Detecting Airdrop Hunters in {NFT} Markets with a Graph Learning System}, author={Zhou, Chenyu and Chen, Hongzhou and Wu, Hao and Zhang, Junyu and Cai, Wei}, booktitle={Proceedings of the ACM Web Conference 2024}, series={WWW '24}, pages={1824--1834}, year={2024}, month=may, publisher={ACM}, doi={10.1145/3589334.3645597}, url={https://doi.org/10.1145/3589334.3645597} } - IEEE Wirel Commun
 Harnessing Web3 on Carbon Offset Market for Sustainability: Framework and A Case StudyIEEE Wireless Communications, 2023
Blockchain, pivotal in shaping the metaverse and Web3, often draws criticism for high energy consumption and carbon emission. The rise of sustainability-focused blockchains, especially when intersecting with innovative wireless technologies, revises this predicament. To understand blockchain’s role in sustainability, we propose a three-layers structure encapsulating four green utilities: Recording and Tracking, Wide Verification, Value Trading, and Concept Disseminating. Nori, a decentralized voluntary carbon offset project, serves as our case, illuminating these utilities. Our research unveils unique insights into the on-chain carbon market participants, affect factors of the market, value propositions of NFT-based carbon credits, and the role of social media to spread the concept of carbon offset. We argue that blockchain’s contribution to sustainability is significant, with carbon offsetting potentially evolving as a new standard within the blockchain sector.
Formatted citationZhou, C., Chen, H., Wang, S., Sun, X., El Saddik, A., and Cai, W. Harnessing Web3 on Carbon Offset Market for Sustainability: Framework and A Case Study. IEEE Wireless Communications, 30(5), 104–111, 2023. doi:10.1109/MWC.010.2300038.
BibTeX@article{zhou2023harnessing, title={Harnessing {Web3} on Carbon Offset Market for Sustainability: Framework and A Case Study}, author={Zhou, Chenyu and Chen, Hongzhou and Wang, Shiman and Sun, Xinyao and El Saddik, Abdulmotaleb and Cai, Wei}, journal={IEEE Wireless Communications}, volume={30}, number={5}, pages={104--111}, year={2023}, month=oct, publisher={Institute of Electrical and Electronics Engineers (IEEE)}, doi={10.1109/MWC.010.2300038}, url={https://doi.org/10.1109/MWC.010.2300038} }